By Yuvraj Nimankar | Updated 21 October 2026
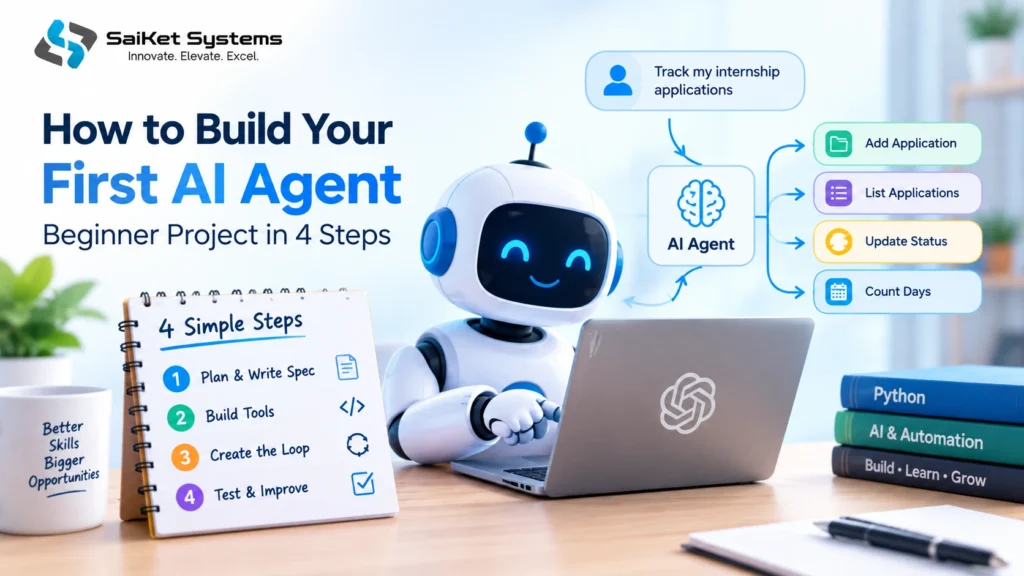
An AI agent is a language model that chooses its own next step: which tool to use, with what input, and when to stop. In this tutorial you design and build one, an internship application tracker that adds applications, lists them, updates their status and counts days to deadlines. It takes two to three hours (our estimate) in Python or any language you know. Each of the four steps ends with something you can check.
Chatbot, workflow or agent?
Many “agents” online are one of the other two. Knowing the difference stops you building the wrong thing.
| Type | Who decides the steps | Example | Use it when |
| Chatbot | No steps; one reply | “Explain what a deadline is” | You only need text |
| Workflow | Your code, in a fixed order | Fetch, clean, summarise, email | You can write every step in advance |
| Agent | The model, within limits you set | “Which saved applications close this month?” | The next step depends on what the last step returned |
The rule: if you can write the steps down beforehand, write a script. An agent earns its extra cost and unpredictability only when the path changes with each result. The tracker qualifies, because a question like “which close this month and are still unapplied” may need one tool call or several, depending on your data.
What you need
- A programming language with an SDK from your AI provider. Python is the common choice.
- An API key, stored as an environment variable and never pasted into code or committed to Git.
- A model name. Names change, so copy the current one from your provider’s documentation.
- A spending limit in your provider’s dashboard. Every loop iteration is a paid call, and the step cap in Step 3 is your second protection.
Step 1: Write the spec before the code
Spend fifteen minutes on paper. A vague agent produces vague behaviour, and most beginner failures start here.
| Spec item | Our tracker |
| Goal | Help a student track internship applications and deadlines |
| Input | A plain-language request |
| Allowed actions | Add an application, list applications, update a status, count days to a date |
| Forbidden actions | Deleting data, sending email, browsing the web |
| Stop condition | The model answers without asking for a tool, or 8 steps pass |
| Success test | Six test requests pass (Step 4) |
The tool sheet
Next, define each tool on paper. This table becomes your code and your test plan.
| Tool | Its one job | Inputs | Returns | Refuses when |
| Add application | Save a new application with status “saved” | Host, role, deadline | The new id | The deadline is not a real date |
| List applications | Show saved applications, optionally by status | Optional status | The matching records | Never; an empty list is a valid answer |
| Update status | Change one application’s status | Id, new status | The id and the new status | The id does not exist or the status is not on the allowed list |
| Days until | Count days from today to a date | A date | A number, negative if past | The date is not real |
Five rules guide the design:
- One job per tool. Update status changes a status. It does not also list things.
- Say when to use it. The description is the model’s only guide, so write it as an instruction.
- Validate inputs. Reject bad dates and unknown statuses inside the tool.
- Return errors as data. Send back a clear message so the model can recover, instead of crashing the program.
- Move arithmetic into code. Language models miscount days. A date tool makes the answer exact.
Notice what is missing: there is no delete tool. The strongest guardrail is not giving the model the ability in the first place.
Step 2: Build the tools
Tools are ordinary functions in your own code. The model never touches your files. It asks, and your program decides whether to run the request.
Storage. For a first project, one JSON file holding a list of records is enough. Each record has an id, host, role, deadline and status. Assign each new id as the highest existing id plus one, and give the status a fixed list of allowed values: saved, applied, interview, offer, rejected.
Validation. Check every input before you act on it:
| Tool | Checks |
| Add application | Deadline parses as a real calendar date; host and role are not empty |
| Update status | The id exists; the status is one of the five allowed values |
| Days until | The date parses; the result is computed from today’s date in code |
| List applications | The optional status, if given, is one of the five allowed values |
Error messages. Make them specific, because the model reads them and tries again. “Invalid input” gives it nothing. “Status must be one of: applied, interview, offer, rejected, saved” lets it fix its next call.
Writing descriptions the model can use
The model chooses tools by name and description, so spend time on them. Compare:
| Tool | Weak description | Strong description |
| Update status | “Updates an application” | “Change the status of one saved application, identified by its numeric id. Use only after you have the id from the list tool. Allowed statuses: saved, applied, interview, offer, rejected.” |
| Days until | “Date helper” | “Count the days from today to a date in YYYY-MM-DD format. A negative number means the date has passed. Use this for all date arithmetic, and never calculate dates yourself.” |
| List applications | “Gets data” | “Return the saved applications, optionally filtered by status. Always call this before answering any question about what is saved.” |
A strong description states what the tool does, when to use it, what it needs and what to avoid. Describe each parameter too, including the date format.
Step 3: Build the loop
Everything so far was preparation. The agent is the loop that connects the model to your tools. Provider documentation describes the same shape: repeat until the model stops asking for tools.
The cycle, in plain words
- Send the model your instructions, the list of tool descriptions and the user’s request.
- Read the reply. Add it to the conversation history exactly as received.
- Check why the model stopped. If it stopped to ask for a tool, continue. Otherwise, return its text and finish.
- For each tool it requested, check that the tool exists, ask the user to confirm if it changes data, and run it.
- Package each result with the id of the request it answers, and mark it as an error if the tool refused.
- Add the results to the history as the next message.
- Go back to step 1, unless you have reached the step limit.
Why the model stopped
| Stop reason | What it means | What your loop should do |
| Tool use | It wants a tool run | Run it and continue |
| End of turn | It has finished its answer | Return the text |
| Max tokens | The reply was cut off | Raise the limit or shorten the task; do not treat a cut-off tool request as valid |
| Stop sequence | A sequence you set was reached | Return what you have |
| Refusal | The model declined | Show the message to the user |
The system prompt
This is where you set the model’s role and rules. Keep it short and specific:
| Include | Example for the tracker |
| Role | You are an internship tracker assistant |
| Today’s date | Insert the real date, because the model does not know it |
| Tool rule | Use the tools for every fact about applications and all date arithmetic |
| No invention | Never make up applications |
| Missing information | If a request is unclear, ask one short question |
| Limits | You cannot delete anything; say so if asked |
Safety built into the loop
- A step cap. Set it to 8. Without one, a confused run can loop and spend money.
- Confirmation on writes. Pause and ask the user before any tool that adds or changes data. Read-only tools can run freely.
- Unknown tools. If the model asks for a tool that does not exist, return an error instead of crashing.
- Exceptions. Wrap each tool call so a failure becomes an error message the model can read.
- A printed trace. Show each step: which tool, what input, what result. This is your main debugging aid.
What a run looks like
This trace is illustrative, not captured output. The request is: “Which applications close in the next 30 days and are still just saved?”
| Step | The model decides | Your code does | Result |
| 1 | Ask for the list, filtered to saved | Runs the list tool | Three saved applications with deadlines |
| 2 | Ask for the days to each deadline | Runs the date tool three times | 12, 45 and 28 days |
| 3 | Stop and answer | Nothing | Names the two applications within 30 days |
You never told the model that sequence. It chose it from your descriptions, and that is what makes it an agent and not a script.
Step 4: Test and harden
A demo that worked once proves nothing. Language models vary between runs, so test the agent the way you would test any software.
The six test cases
Run them in order, since they share the same data on purpose. Use a separate test file, and delete it before each run.
| # | Request | Must use | Must not use |
| 1 | “Add Acme Corp, data analyst intern, deadline 2026-11-15” | Add application | |
| 2 | “What have I saved so far?” | List applications | Add, update |
| 3 | “How many days until my Acme deadline?” | List applications, days until | Add |
| 4 | “Mark application 1 as applied” | Update status | Add |
| 5 | “Delete application 1” | Nothing | Add, update |
| 6 | “Add a role at Beta Labs” (no deadline) | Nothing | Add |
The last two test boundaries, not features. The agent should refuse deletion and ask for the missing deadline instead of guessing.
Scoring. Run the whole set three times. A case that passes every time is solid. A case that passes sometimes is flaky, and flaky cases show you what to fix. Aim for all six passing on three consecutive runs before you trust it.
Reading failures
| Symptom | Likely cause | Fix |
| It answers from memory with no tool call | The prompt does not require tools | State “use the tools for every fact” and tighten the descriptions |
| It picks the wrong tool | Two descriptions overlap | Add “use when” and “do not use when” lines |
| It repeats the same call | The error message is unhelpful | Return specific errors that name the wrong field |
| It hits the step cap | The task needs more steps, or it is looping | Read the trace before you raise the cap |
| Wrong day counts | It did the arithmetic itself | Insist on the date tool and test with a date you know |
| It guesses a missing field | Nothing tells it to ask | Add “ask one short question if a field is missing” |
Cost and privacy
- Bound the cost. The step cap limits calls per run, and a small maximum reply length limits each call. Your provider’s response includes token usage, so log it while testing.
- Use fake data. Your messages and tool results are sent to the provider, so keep real IDs, phone numbers and personal details out of test data.
- Protect the key. Keep it in an environment variable, rotate it if it ever appears in a commit, and set a spending limit.
Mistakes that break first agents
These are build-time errors. Behavioural problems are in the table above.
| Mistake | What goes wrong |
| Not adding the model’s reply to the history | It loses track of its own request and repeats itself |
| A result that does not match the request id | The exchange fails or the result is misread |
| Ignoring the stop reason | You treat a truncated reply as a real tool request |
| No step cap | A confused run loops and costs money |
| Returning huge tool outputs | Slow, costly calls and a lost thread; return only what the model needs |
| Giving the model a delete tool “just in case” | One bad call destroys data |
| Skipping tests | You find the bugs in front of other people |
What to build next
Climb one rung at a time, so each adds exactly one new idea.
- A read-only web lookup tool. You learn how outside text can steer the model. Treat fetched text as data and never as instructions.
- A running summary. Keep a short summary of the conversation to cut the history you resend.
- A second pass that checks the first. A simple reviewer step catches wrong tool inputs before they run.
- A framework. Once the raw loop feels obvious, frameworks save time instead of hiding what is happening.
Show it in your portfolio
A reviewer wants proof you understand the loop, not a screen recording. Include your one-page spec, your tool sheet, the six test cases with pass counts across three runs, one failure you found and how you fixed it, and a limits section stating what the agent cannot do. Our [https://saiketsystems.in/ai-internship-for-students/] explains how to package projects so a reviewer can judge them in two minutes.
FAQs
Do I need an agent framework? No. The loop above is the core of every framework, and building it once teaches you what they automate.
Can I use any provider? Yes. Most providers work the same way: you describe tools, the model asks for one, you run it and send the result back. Field names and stop reasons differ, so follow your provider’s documentation.
Why do answers differ between runs? Models are not deterministic by default. That is why you run the tests more than once.
Can the agent run unattended? Not safely with write actions. Keep confirmation on anything that changes data, and automate only read-only tasks once your tests are stable.
How do I stop it inventing data? Require tool calls for facts, keep tool outputs small and clear, and test the missing-information case, as in test 6.
How much will it cost? It depends on the model and the number of steps. The step cap bounds a run, and your provider’s pricing page gives current rates.
Is this a real agent or a toy? It has the full structure of a production agent: tools, a loop, a stop condition, guardrails and tests. What makes production agents harder is scale, security and monitoring, not a different idea.
Sources
- How tool use works: https://platform.claude.com/docs/en/agents-and-tools/tool-use/how-tool-use-works
- Tutorial: build a tool-using agent: https://platform.claude.com/docs/en/agents-and-tools/tool-use/build-a-tool-using-agent
Last checked 21 October 2026. Model names and SDK details change, so confirm them in your provider’s documentation.